AI News for August 24, 2026
Browse any day on a calendar, install it to your home screen, read offline.Read in the app →-
1TechCrunch04:01
Who's behind the new ‘stealth model’ Ox Alpha?
A model called Ox Alpha has surfaced with no vendor claiming it, and the community is working backward from its output style and capability profile to guess the lab behind it. Anonymous "stealth" releases are a common way for large labs to run live tests and collect head-to-head battle data before an official launch, so the model's performance is treated as a preview of the next generation's baseline.
Read original ↗ -
2TechCrunch23:00
Is it legal to train AI models on copyrighted books? It’s complicated
Large numbers of authors have had their books used as training data without knowledge or consent, feeding tools that now compete with their livelihoods. Courts remain split on three questions — the limits of fair use, how the training data was obtained, and whether model output substitutes for the original works — and the answers will determine whether AI companies face far higher data acquisition costs.
Read original ↗ -
3TechCrunch23:30
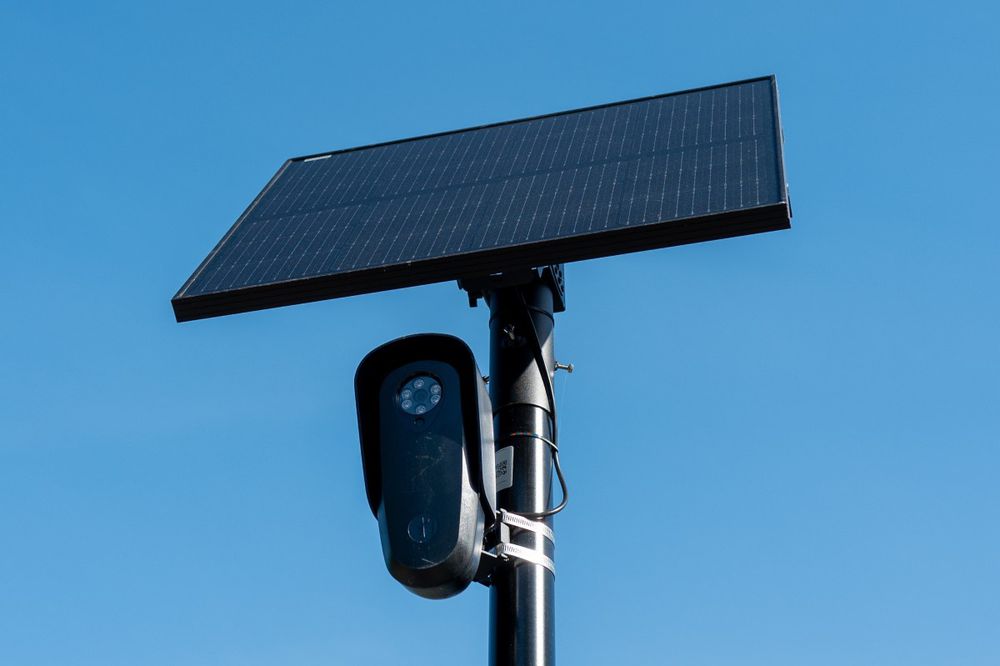
Flock CEO calls for ‘compromise’ as surveillance company faces growing backlash
Flock Safety's license plate recognition and video analysis systems are drawing intensifying public opposition over potential misuse, and the company's CEO has publicly called for a regulatory compromise. The case marks the shift of computer vision products from a technical question to one of public governance, pushing teams deploying similar systems to build usage limits and audit mechanisms into the product itself.
Read original ↗ -
4VentureBeat07:00
Enterprise AI agents are only as reliable as the messiest documents behind them
Most enterprises today build context engineering around a single application — connecting systems, chunking documents, generating vectors, and wiring up retrieval — which works for an isolated assistant but treats institutional knowledge as one app's private context rather than a shared asset. The argument is to make the knowledge layer shared infrastructure; otherwise every new agent repeats the same cleanup work, and reliability stays capped by the worst-maintained documents in the corpus.
Read original ↗